Insights
Weekly digest · Week of Aug 31, 2026

The frontier agreed on $10 and $50

Anthropic and OpenAI shipped flagships at the same list price with cache reads four times apart, and a two-year school trial found AI tutoring matched practice without it.

Economics
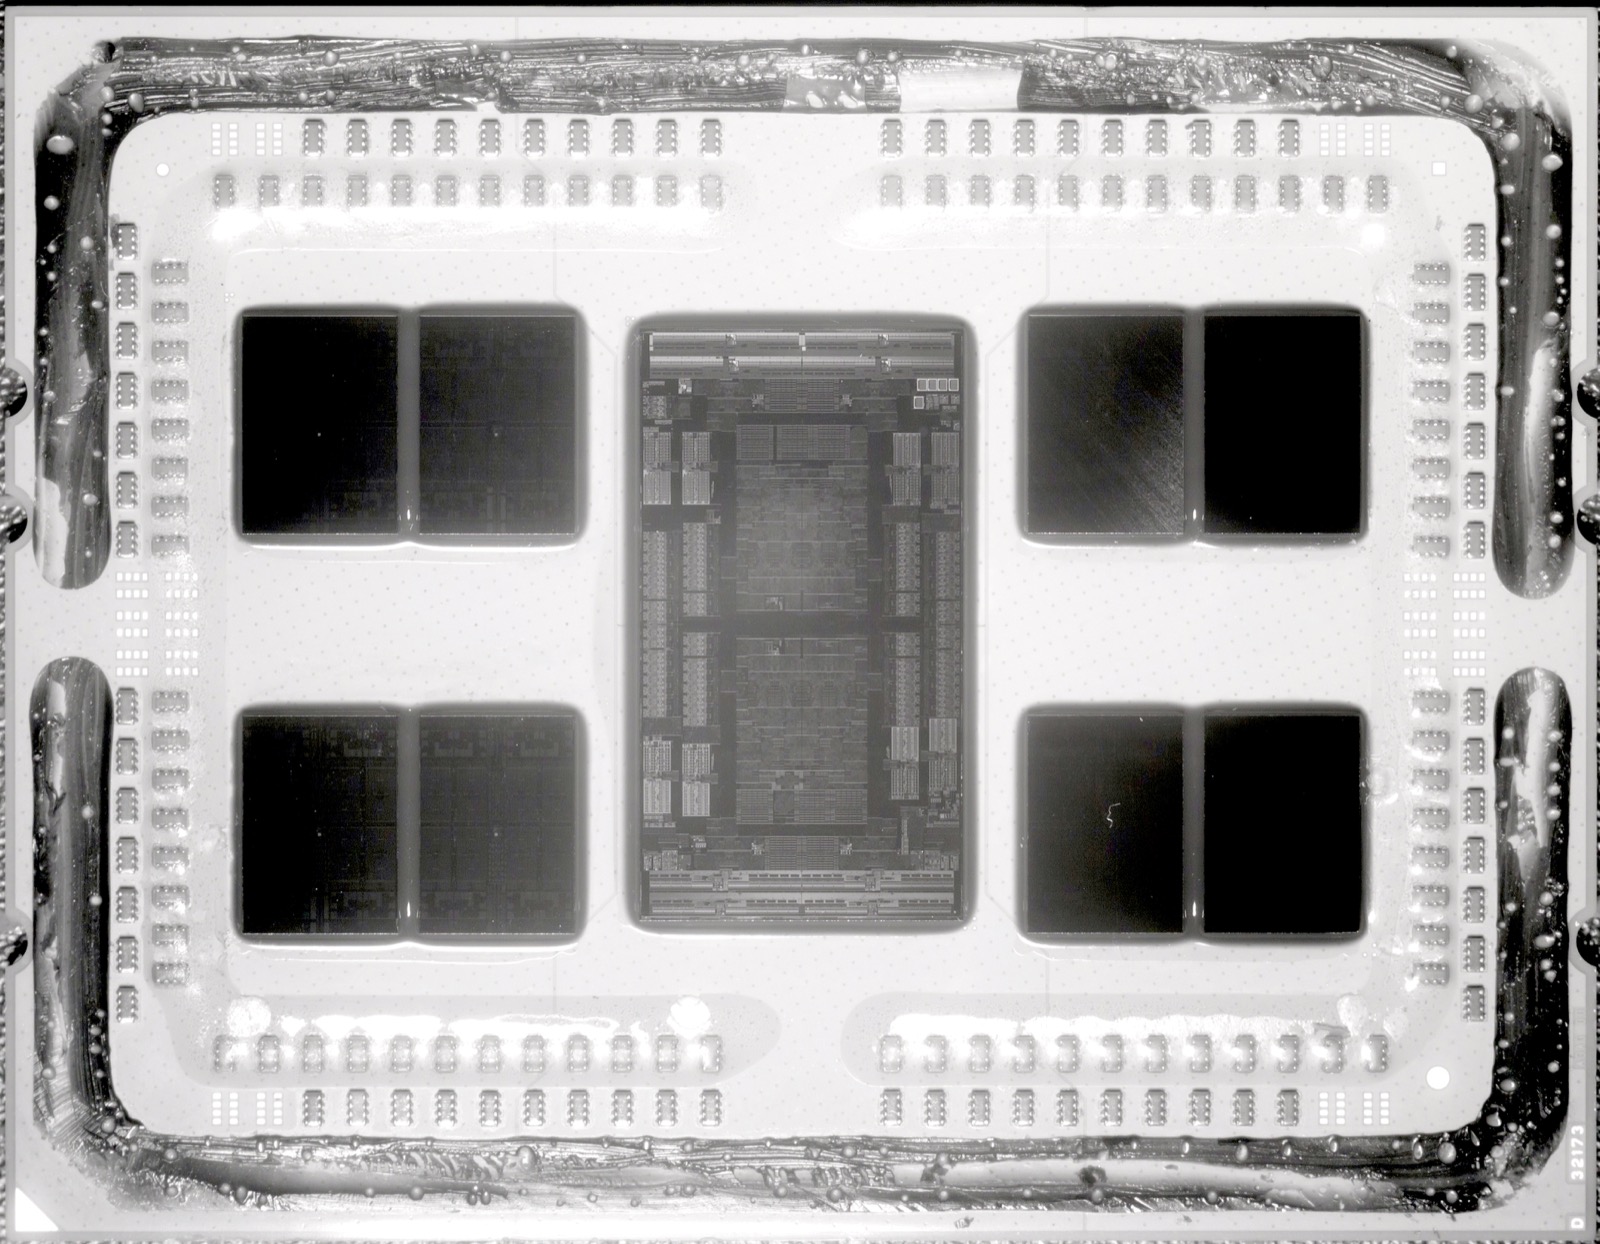
A delidded server processor photographed in near infrared, the IO die in the middle and eight core chiplets around it.
Fritzchens Fritz / Wikimedia Commons · CC0

What a cached token costs

Reading a million cached tokens back into Claude Fable 5.1 now costs 75% less, or $0.25. Anthropic left the rest of the card alone, at $10 per million input tokens and $50 per million output, and puts the saving at around 25% for typical workloads and up to around 45% for complex coding and highly agentic tasks, measured over four weeks of its own August usage.

Two days later OpenAI listed GPT-6 Astra at $10 for a million input tokens, $50 for a million output and $1.00 for cached input, the same sticker on the first two numbers and four times Anthropic's price on the third. On long-context requests the same model costs $20, $75 and $2.00. Cached reading now costs a tenth of the input price at OpenAI and a fortieth at Anthropic.

On context-heavy, tool-heavy work, Anthropic says cache reads make up most of the cost. An agent re-reads the system prompt, the repository and the transcript on every turn. The discount is aimed at that workload, and it is invisible on a comparison sheet that carries two numbers per model. For agentic work the number that decides the bill is 25 cents against a dollar.

Metric move

Our own basket records list input and output only, and every Anthropic and OpenAI model in it came back unchanged. What moved was DeepSeek V4 Pro, whose cheapest listed route fell to $1.04 and $2.08 a million tokens from $1.60 and $3.20, taking the support-assistant floor to $271 a month from $416. All four neocloud GPU ranges held for a fourth week.
Spotlight
A junior high computer classroom, students working through an on-screen exercise at desktop machines.
褒忠國中 雲端網 / Wikimedia Commons · CC BY 2.0

The tutor the students rarely talked to

Every struggling student is meant to get a tutor, and no district can staff one for each of them.

NBER (Oreopoulos & Low), Aug 1, 2026. A two-year cluster randomized trial by academic researchers, run inside a district's existing remedial maths sessions with the platform's own usage data.

How it works

A chat tutor sits beside each practice exercise, configured to coach a student through the mistake rather than hand back the answer.

The economics

Assignment raised maths achievement 1.3 national percentile ranks per term, roughly 0.06 to 0.08 standard deviations over a school year. The gains resemble the same platform without the AI tutor.

Who it’s for

Education leadership, Product owners, Adoption and enablement.

Transferable pattern

Rolling an assistant out is not the same as getting it used, and this trial measured the gap rather than assuming it away. The same pattern fits support desks, internal copilots and clinical documentation.

Players to watch
NameWhat they doHQStagePosition
Khan AcademyRuns the practice platform and the tutor testedMountain View, CaliforniaInstitutionPlatform
Hamilton County SchoolsThe Tennessee district the trial ran inChattanooga, TennesseeInstitutionAdopter
Carnegie LearningAdaptive maths courseware sold to K-12 districtsPittsburgh, PennsylvaniaMatureSpecialist
PearsonCourseware and assessment incumbent in schoolsLondonListedIncumbent
DuolingoConsumer learning app, now with maths coursesPittsburgh, PennsylvaniaListedChallenger
Signals

Our research reads the structure under an innovation market: the economics, the technology, the ecosystem that connects them. .

New research, by email

Insights